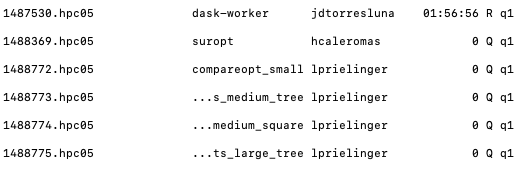
Hi recently the queuing time is much longer than usual. My jobs have been waiting for 3 hours even though the monitoring page suggests that almost all cores (872) are free?
A colleague of mine is facing the same issue.
Can you help us out here?
Hey @anton-akhmerov , I use the qstat command to check the status “R” or “Q”. I submitted the following jobs yesterday (lprielinger) and just checked: they are still in the “Q” status.
I think the issue is related to the size of the requested resources – I tried different test submissions now
#PBS -l nodes=1:ppn=25 got the “R” status within a few seconds #PBS -l nodes=1:ppn=30 stayed in “Q” for 1min then I cancelled the job
In my initial script I specified #PBS -l nodes=3:ppn=30. I wonder if this is simply too large, but then previous submissions of the same size were usually accepted?
You seem to be asking for 30 cpu cores per node. Each node has 2x10 core CPUs with 2x hyperthreading, so they show up as 40 CPU cores. I believe that for practical purposes using more than the amount of physical cores does not provide speedup, and therefore I believe you’re better off not using more than ppn=20. Still, I don’t actually know why ppn=30 doesn’t run unless all nodes have more than 10 cores reserved.
 recently the queuing time is much longer than usual. My jobs have been waiting for 3 hours even though the monitoring page suggests that almost all cores (872) are free?